

Prerequisites
- A dev environment with Node.js, npm, and a terminal installed
- A computer with at least 16gb RAM
- Ideally, a fast internet connection; otherwise downloading models might take a while.
Locally running LLMs: why and how
Running LLMs on your own hardware has a few advantages over using cloud-provided models:- Enhanced data privacy. You are in control and can be confident you’re not leaking data to a model provider.
- Accessibility. Locally running models work without an internet connection.
- Sustainability and reduced costs. Local models take less power to run.
Choosing our models
Ultimately, which model to choose is an extremely complex question that depends on your use case, hardware, latency, and accuracy requirements. Reasoning models are designed to provide more accurate answers to complex tasks such as coding or solving math problems. DeepSeek made a splash releasing their open source R1 reasoning model in January. The open source DeepSeek models are distillations of the Qwen or Llama models. Distillation is training a smaller, more efficient model to mimic the behavior and knowledge of a larger, more complex model. Let’s pit the distilled version against the original here and see how they stack up. In this post, we’ll use small versions of these models (deepseek-r1:1.5b and qwen:1.8b) to make this tutorial accessible and fast for those without access to advanced hardware. Feel free to try whatever models best suit your needs as you follow along.Installing and configuring Ollama
Head to the Ollama download page. Follow the instructions for your operating system of choice. To install our first model and start it running, type the following command in your terminal:/bye command.
Follow the same process to install qwen:1.8b:
Connecting Ollama with a Node.js project
Run the following commands to set up a new Node.js project:Adding a custom model to AgentControl
Head over to the model configuration page on LaunchDarkly UI. Click the Add AI model config button. Fill out the form using the following configuration:- Name: deepseek-r1:1.5b
- Provider: DeepSeek
- Model ID: deepseek-r1:1.5b
- Name: qwen:1.8b
- Provider: Custom (Qwen)
- Model ID: qwen:1.8b
- Name: deepseek-r1:1.5b
- Model: deepseek-r1:1.5b
- Role: User. (DeepSeek reasoning models aren’t optimized for System prompts.)
- Message: Why is the sky blue?
- Name: qwen:1.8b
- Model: qwen:1.8b
- Role: User
- Message: Why is the sky blue?
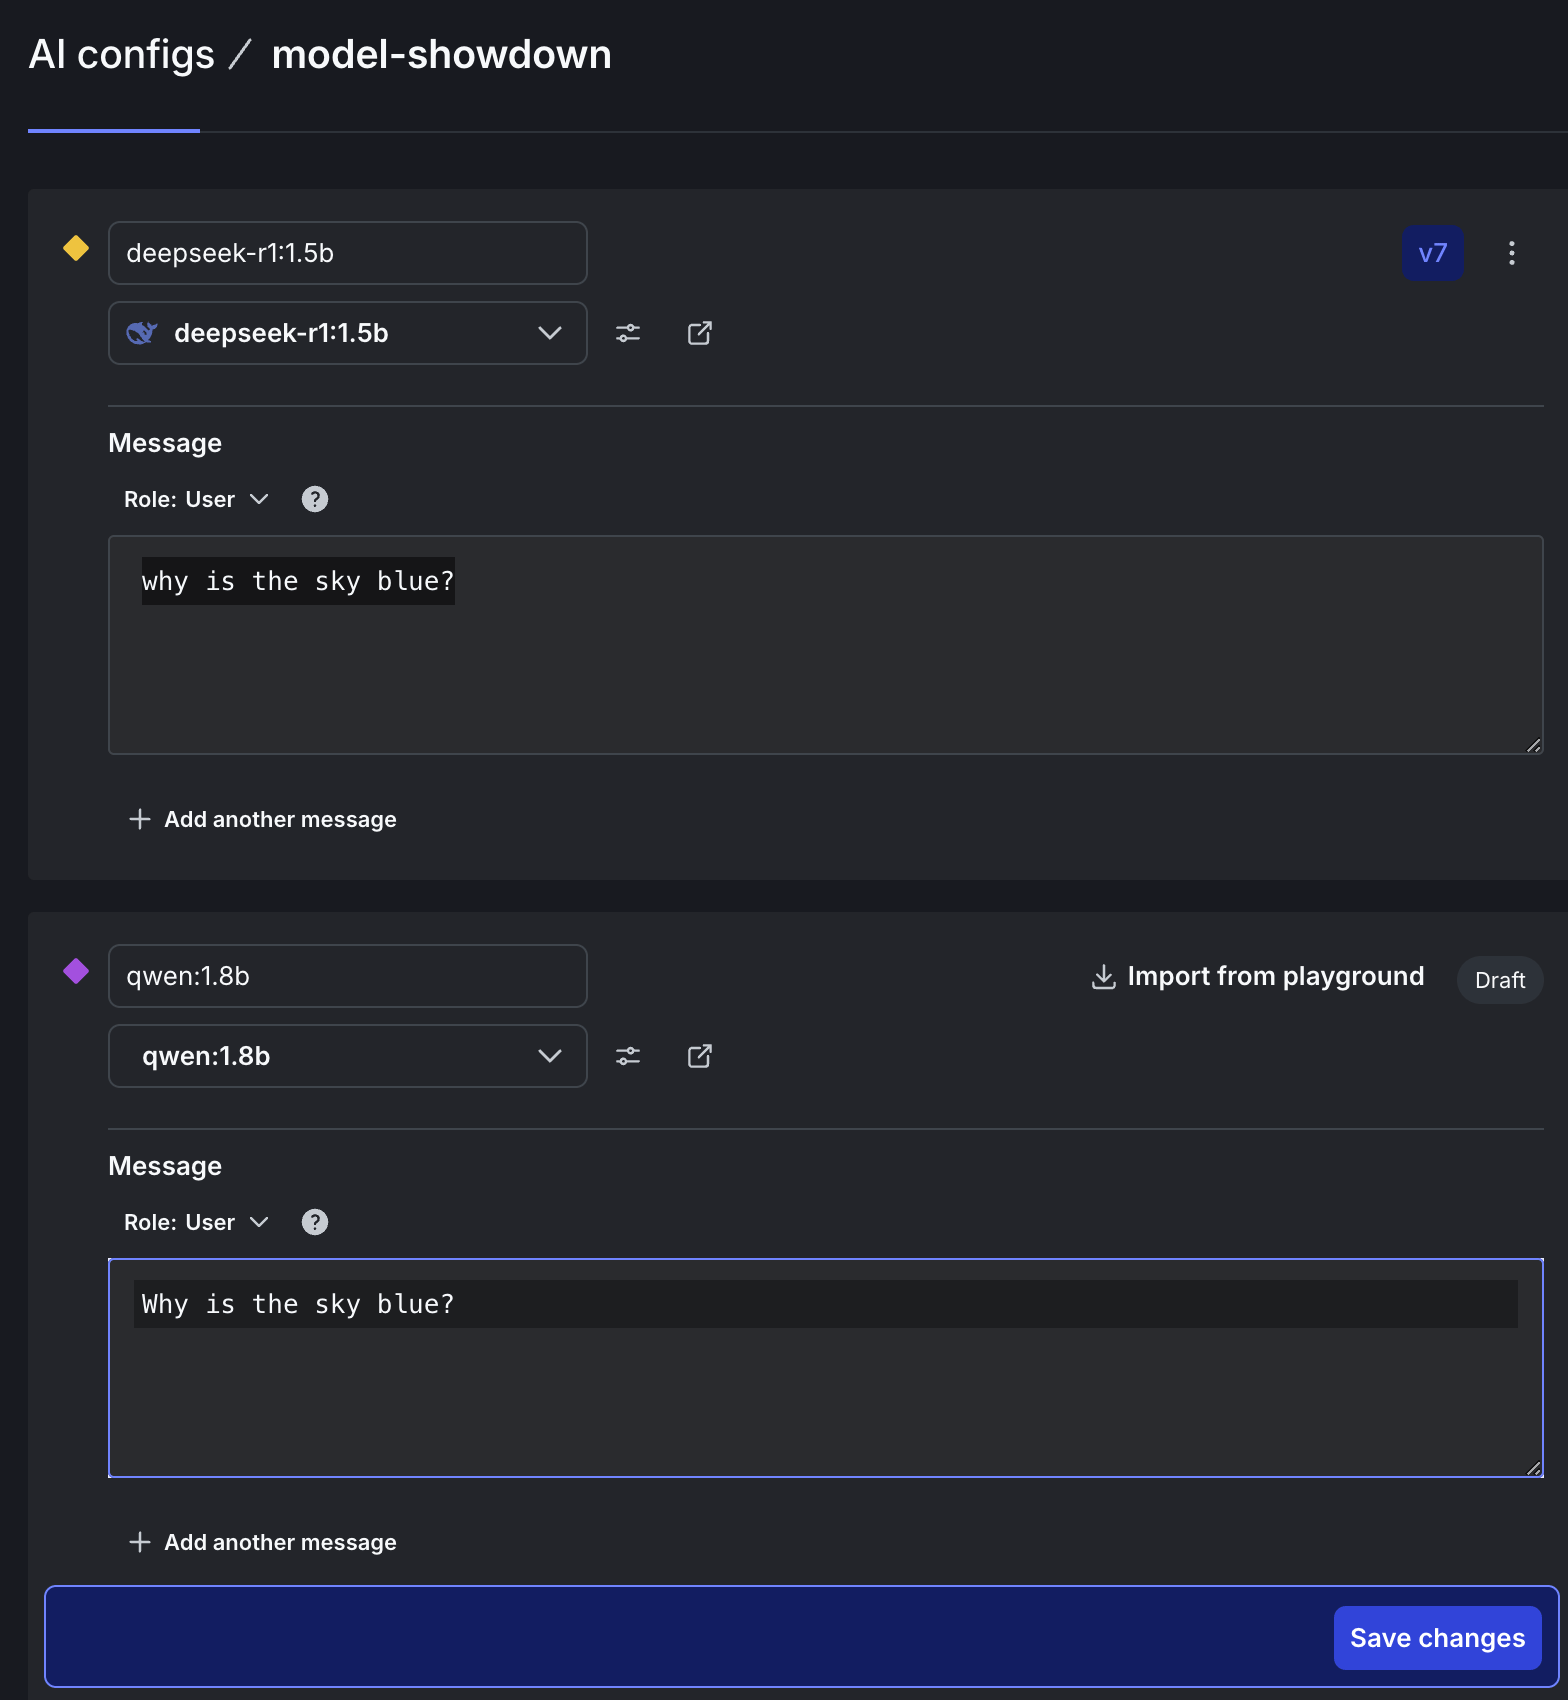
Variations of the models we are using, in the LaunchDarkly UI.
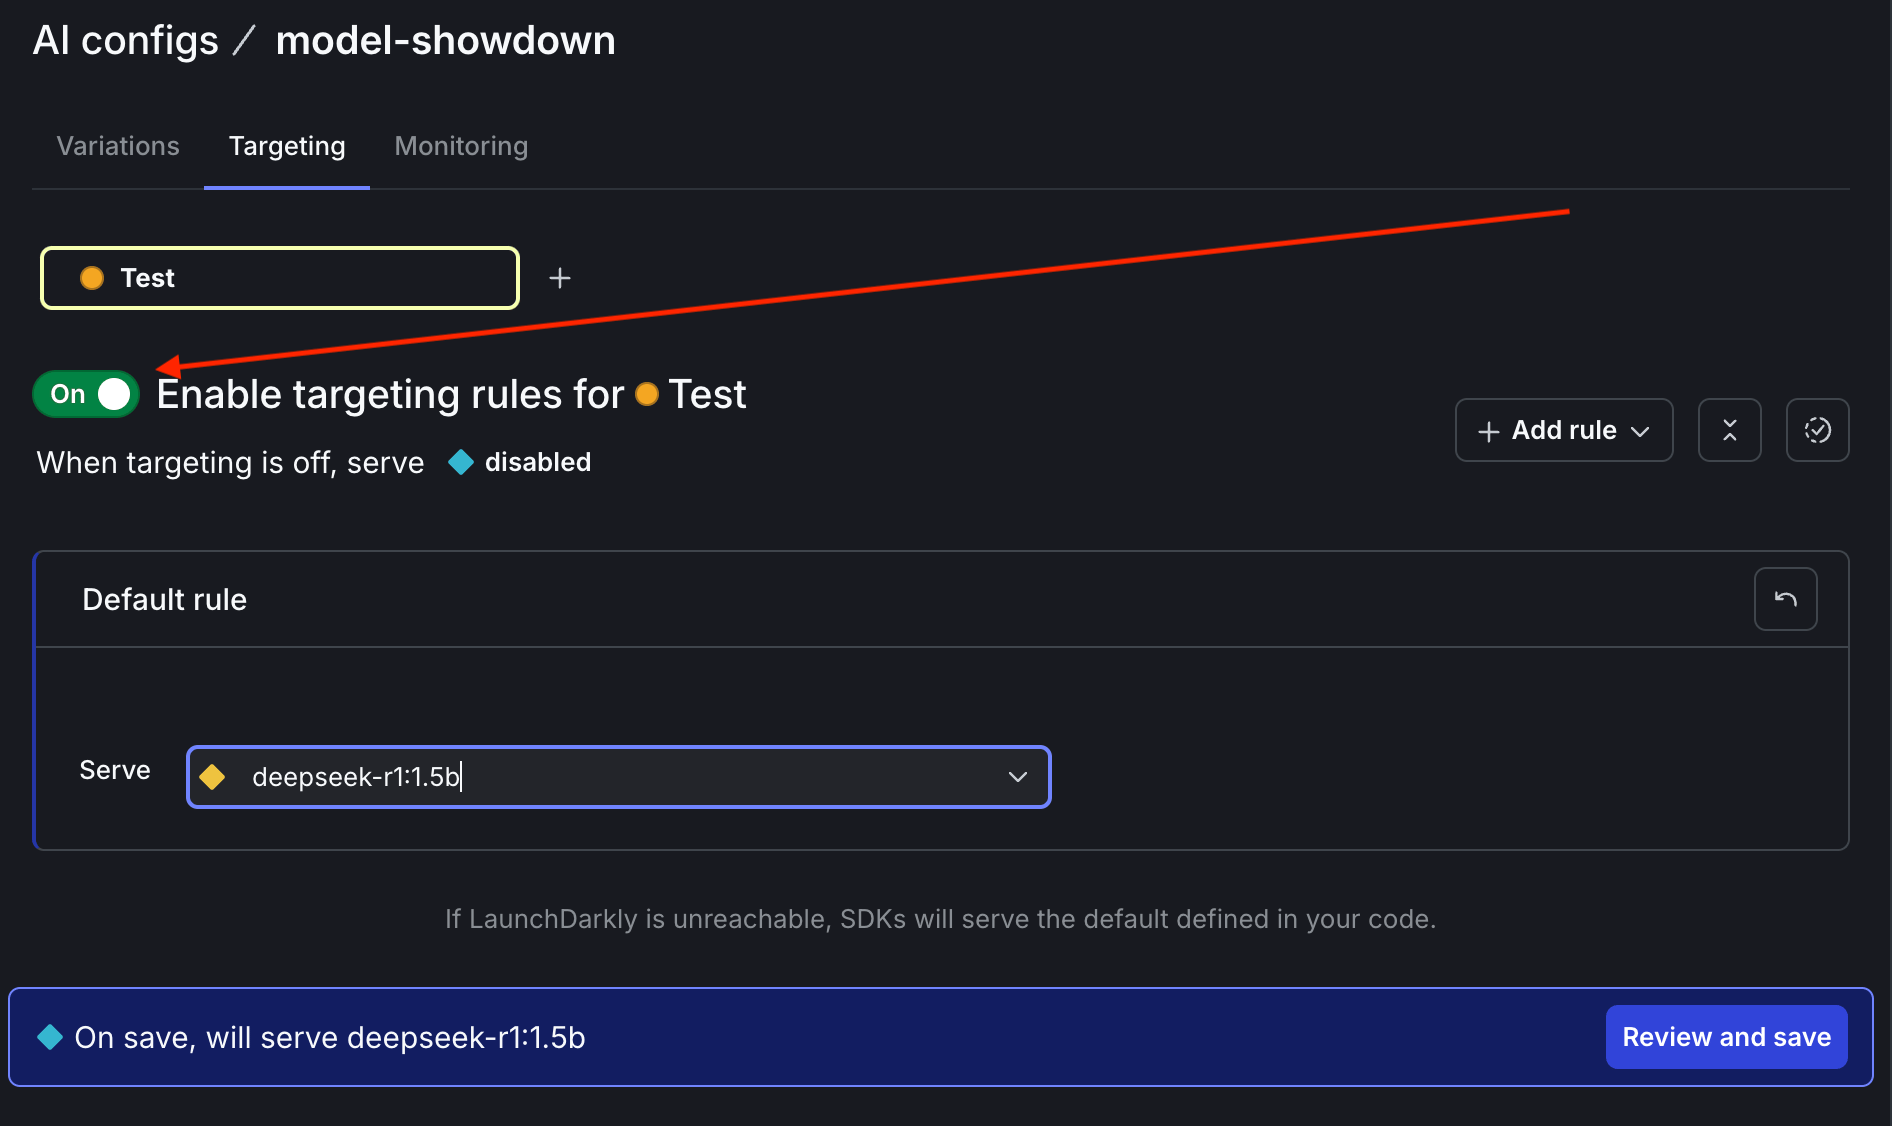
How to target and serve config variations in the LaunchDarkly UI.
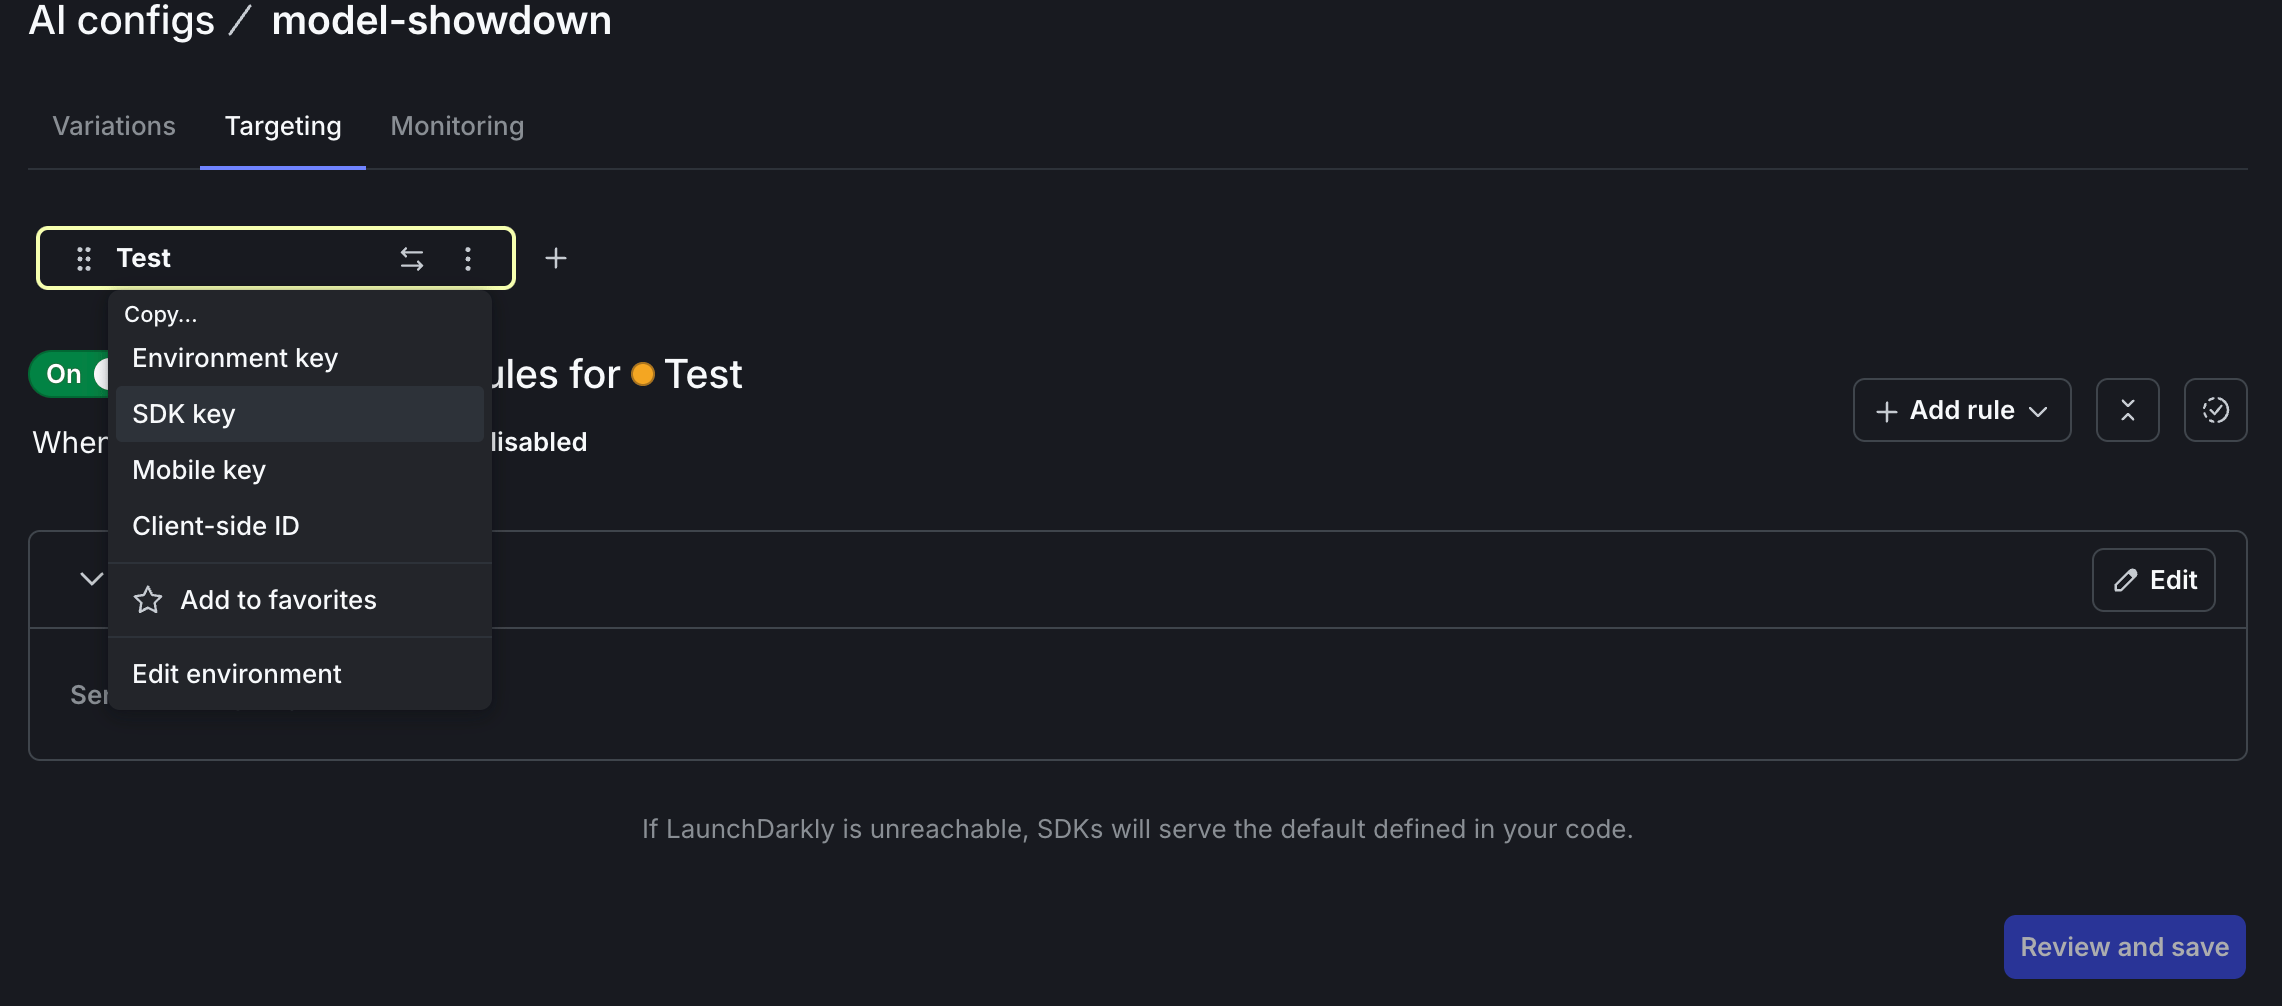
How to copy your SDK key from a project in the LaunchDarkly UI.
Connecting AgentControl to Ollama
Back in your Node project, create a new file named generate.js. Add the following lines of code:node generate.js in your terminal. Output should show the response comes from deepseek-r1:1.5b.
qwen:1.8b model. Save changes.
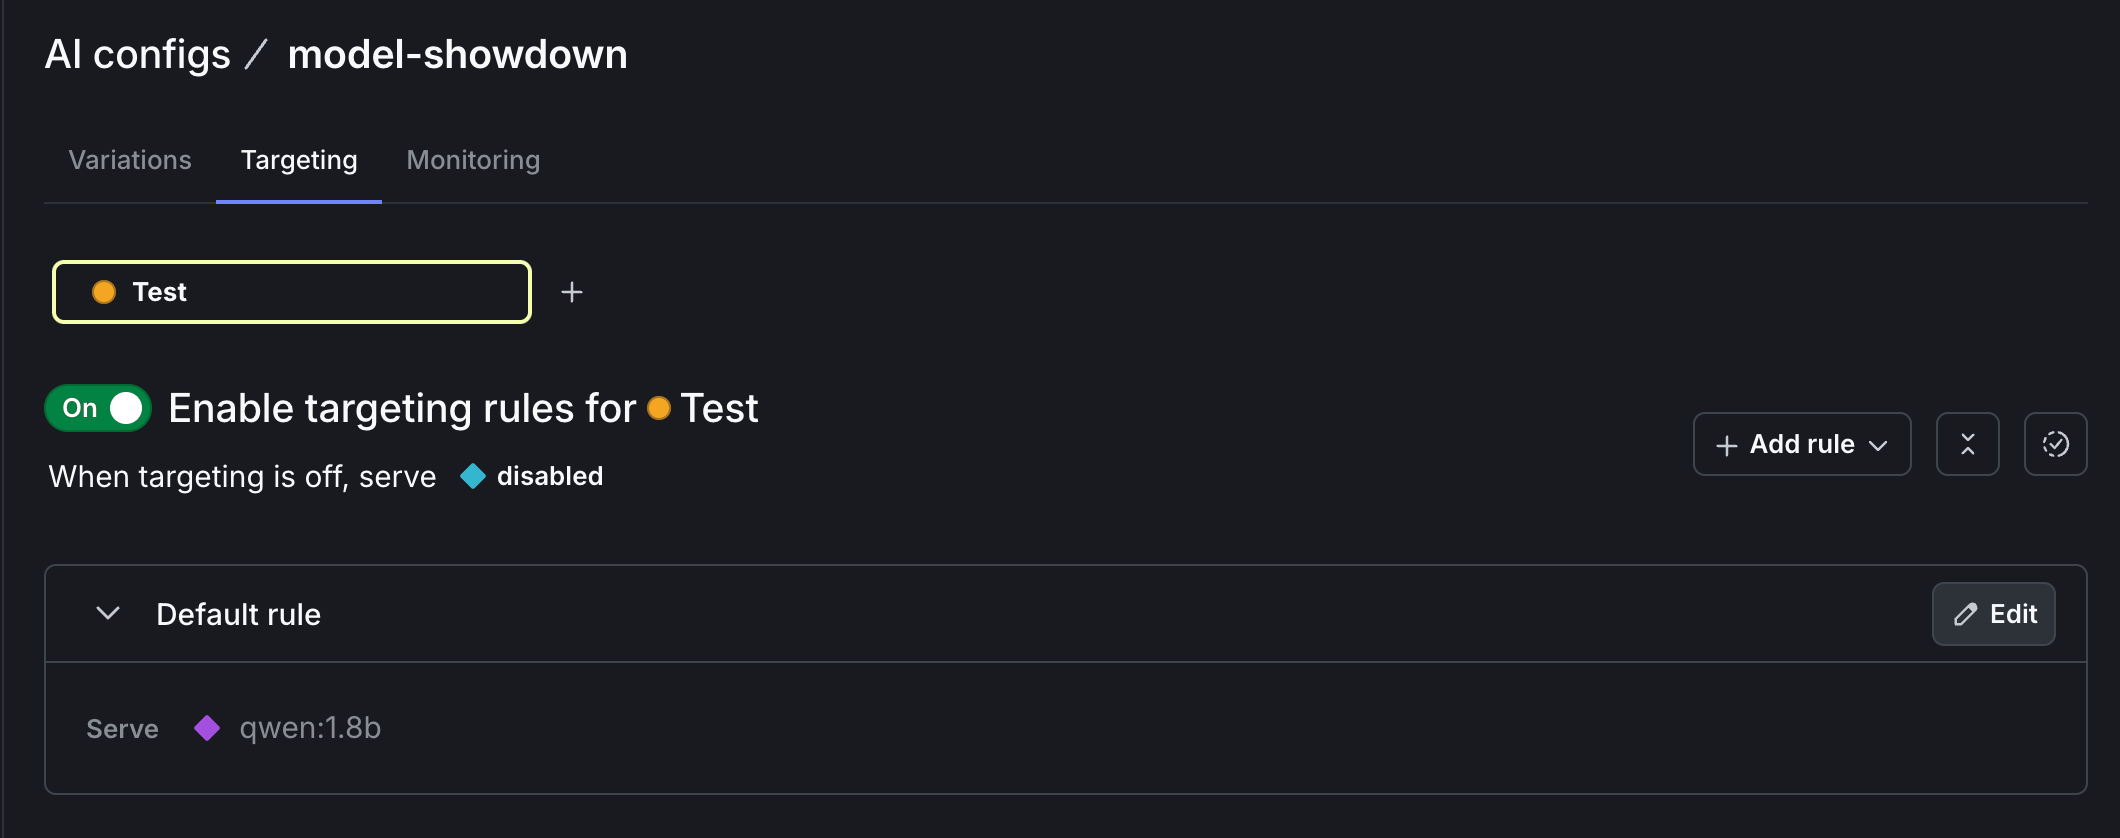
How to serve the Qwen variation.
generate.js and you’ll see the response from qwen:1.8b:
- What is 456 plus 789?
- What is the color most closely matching this HEX representation: #8002c6 ?
trackMetrics in our app, the data we send is visualized in the Monitoring tab on the LaunchDarkly app. Our code tracks input and output tokens, request duration, and how many times each model was called (generation count).
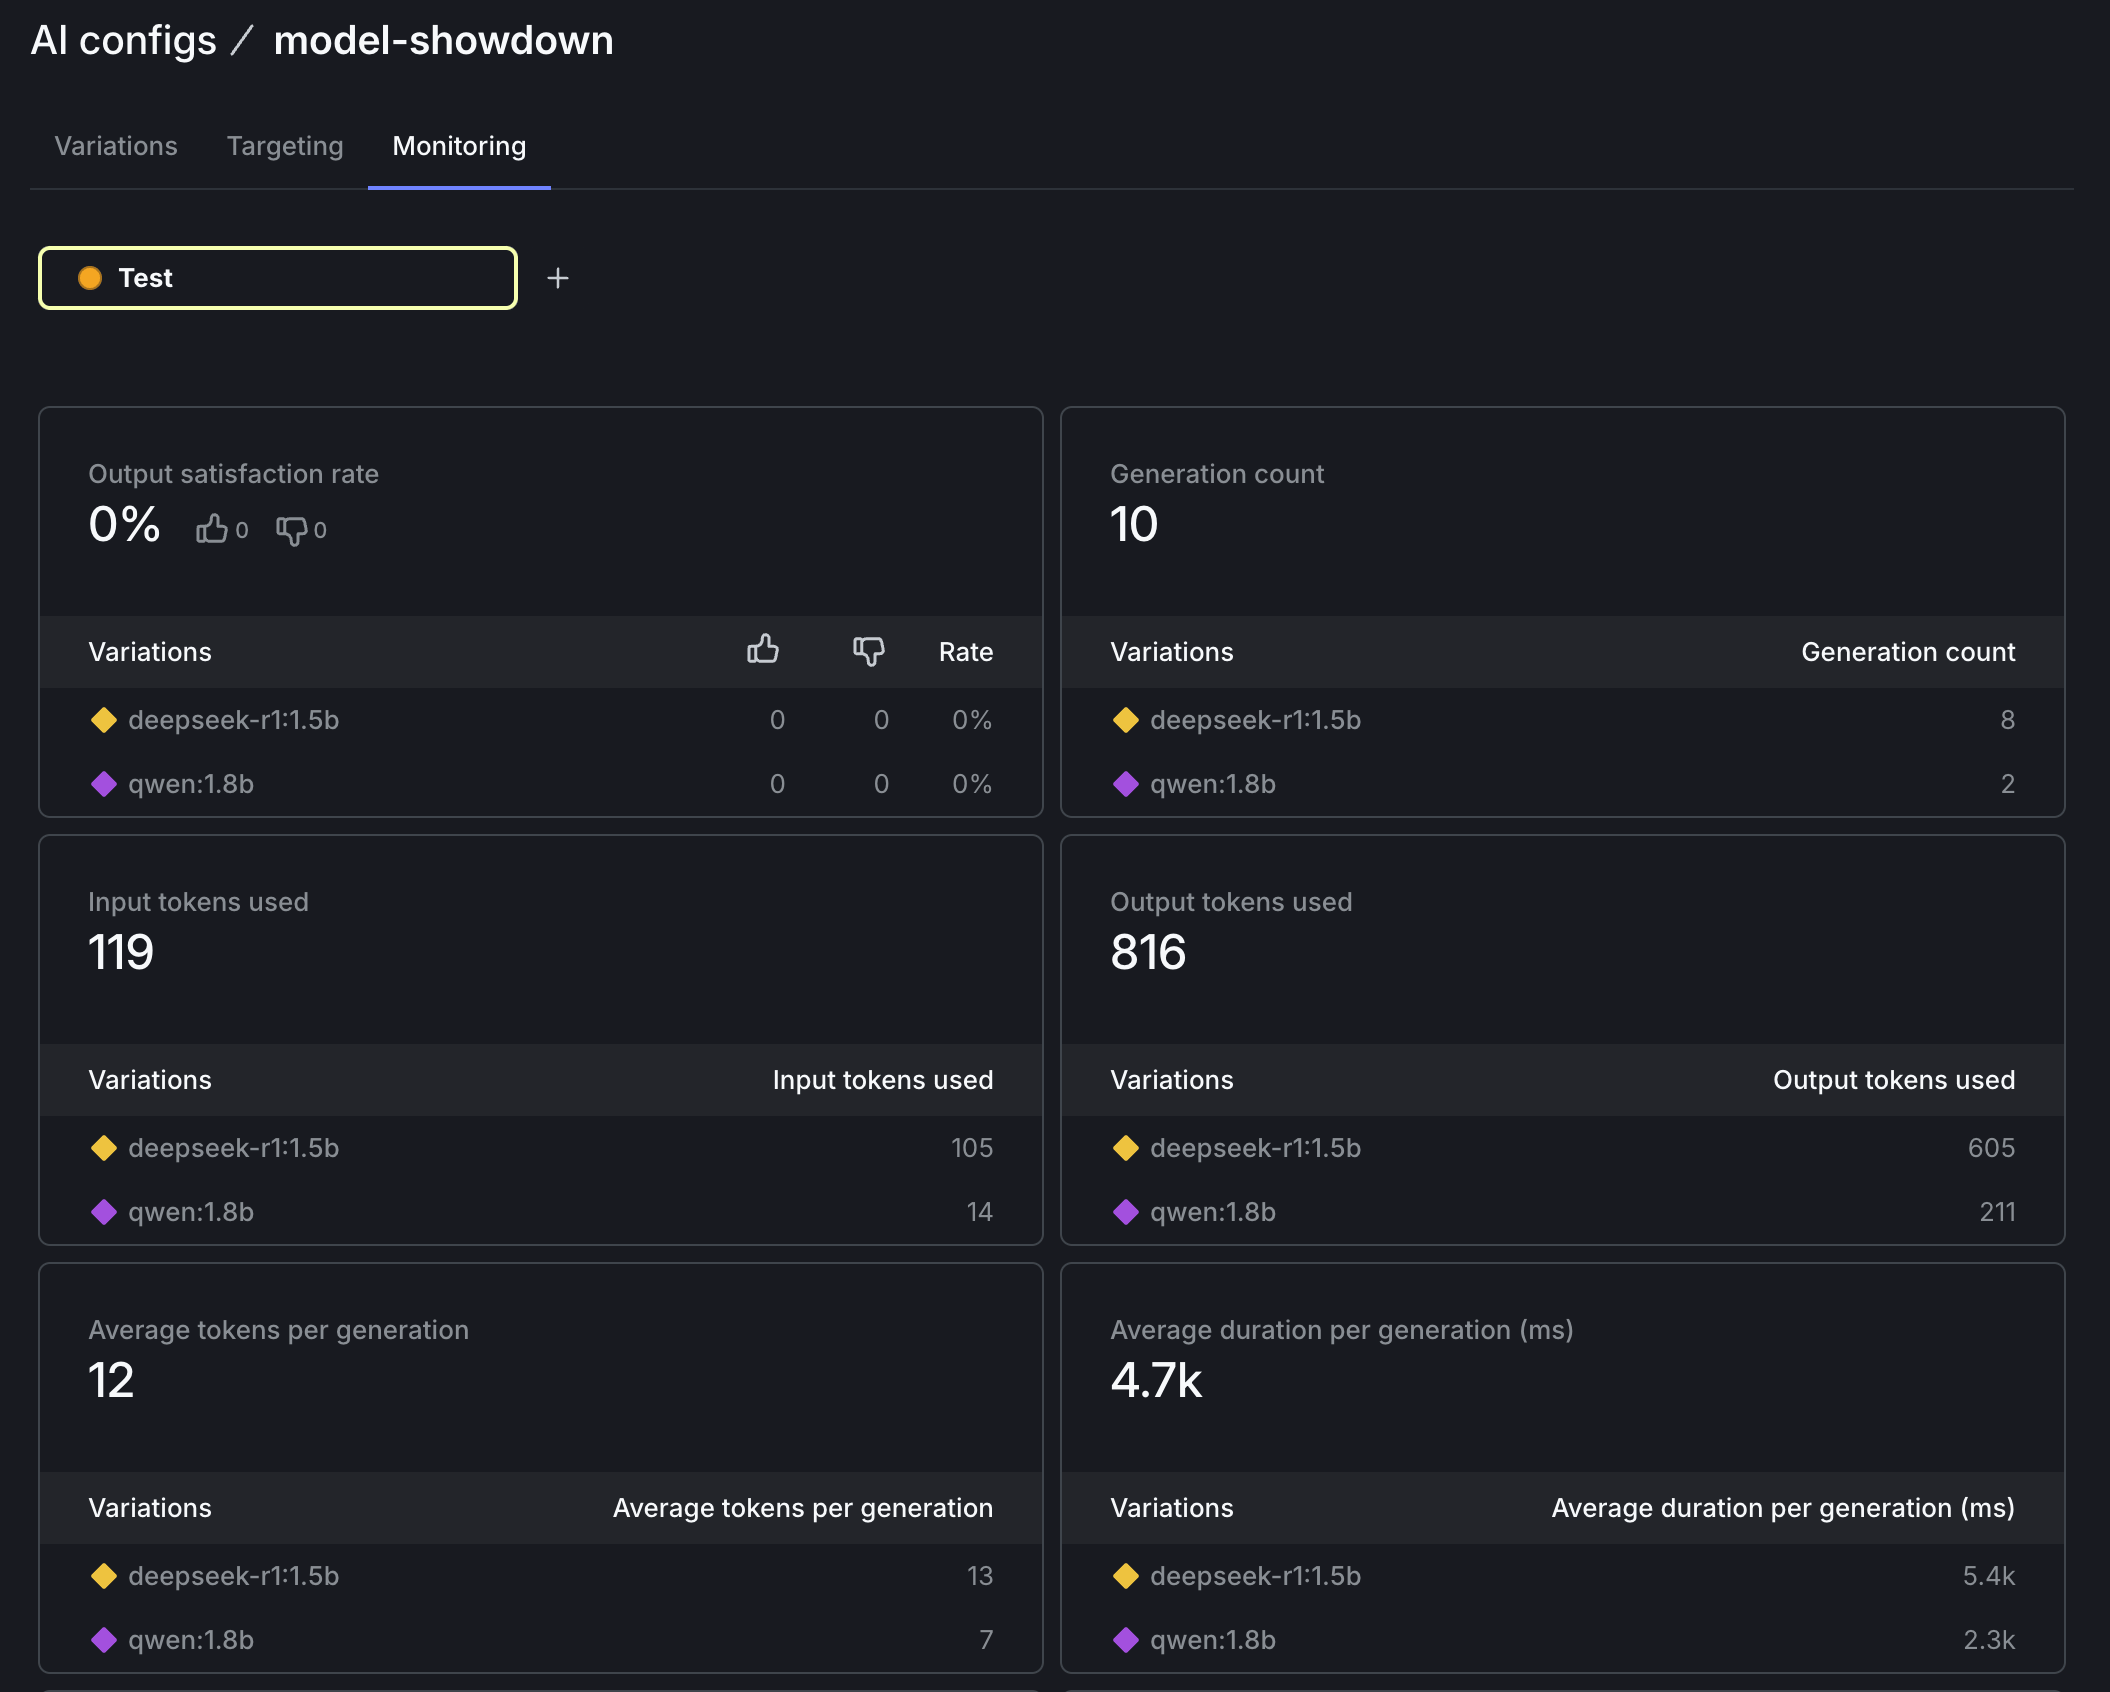
The metrics you can see on the Monitoring tab for each config variation.
Wrapping it up: bring your own model, track your own metrics, take the next steps
In this tutorial you’ve learned how to run large language models locally with Ollama and query the results from a Node.js application. Furthermore, you’ve created a custom model config with LaunchDarkly that tracks metrics such as latency, token usage, and generation count. There’s so much more we could do with AgentControl on top of this foundation. One upgrade would be to add additional metrics. For example, you could track output satisfaction and let users rate the quality of the response. If you are using LLMs in production, AgentControl even supports running A/B tests and other kinds of experiments to determine which variation performs the best for your use case using the power of statistics. AgentControl also has advanced targeting capabilities. For example, you could use a more expensive model for potentially high-value customers with enterprise-y email addresses. Or you could give users a more linguistically localized experience by serving them a model trained in the language specified in their accept-lang header. If you want to learn more about runtime model management, here’s some further reading:- Compare AI Models in Python Flask Applications — Using AgentControl
- Upgrade OpenAI models in ExpressJS applications — using AgentControl