The AI Software Factory Doesn't End at Deploy
A guide to using automated release controls for faster, safer delivery of agent-written code.
AI has moved the bottleneck
Coding agents have increased the volume and velocity of software changes, and most organizations have the PR graphs to prove it. But faster code creation doesn’t automatically translate into more customer value. Instead, the bottleneck has moved downstream, into stages of the SDLC where the processes we’ve always relied on can’t handle the load.
A September 2026 National Bureau of Economic Research study of more than 100,000 developers shows how much of those gains don’t make it into production. According to its data, developers working alongside coding agents produce 958% more lines of code and 86% more PRs, but only 20% more releases.
Today, the strain is most palpable in the review queue, where AI-generated changes pile up faster than human engineers can actually vet them. An August 2026 Harvard study of more than 700 firms found that coding agents increased lines of code by 30% and PRs by 23%, with no matching gain in firm-level output. Over the same period, the average time for a PR to get through review and merge grew from seven days to 10.
As stark as those numbers are, they don’t capture the lived experience of the teams who are responsible for review. Engineers are being asked to review a growing volume of AI-generated code they didn’t write and don’t fully understand, and they’re still accountable for what ships. The problem is so pervasive that it’s become a meme, where “LGTM” is the punchline and production is the butt of the joke.
Many teams are responding by investing in necessary but insufficient measures, such as automated testing and code review agents. These tools can help clear the review queue faster, but none of them can reproduce every production dependency, traffic pattern, data state, or user action. This leaves the release process to absorb the risk, and because release still moves at human speed, it becomes the new bottleneck.
The gap between what clears review and what holds up in production is already visible in the data. In New Relic’s 2026 State of AI Coding report, 94% of technology leaders rated AI-generated code as higher quality than human-authored code at the point of review. Yet 78% reported more incidents after that code shipped, and 86% said their senior staff was spending more time fixing it.
With automated testing and review unable to catch every issue, teams are left with an impossible choice: Either slow down and manually apply release controls to every change, or accept the uncertainty that comes with agent speed. Neither option delivers the ROI that leaders expect from their AI investment, and neither creates the conditions under which engineers can do their best work.
Getting out of that bind requires teams to rethink where the AI software factory begins and ends. Most of the software factory conversation today focuses on automating code generation, testing, review, and deployment. Better code review and testing are essential, but they can’t eliminate production risk. The way to realize the full value of AI-led development is to automate how changes are released, measured, and managed in production, so release keeps pace with code creation while becoming safer and more controlled.
What’s missing from most software factories
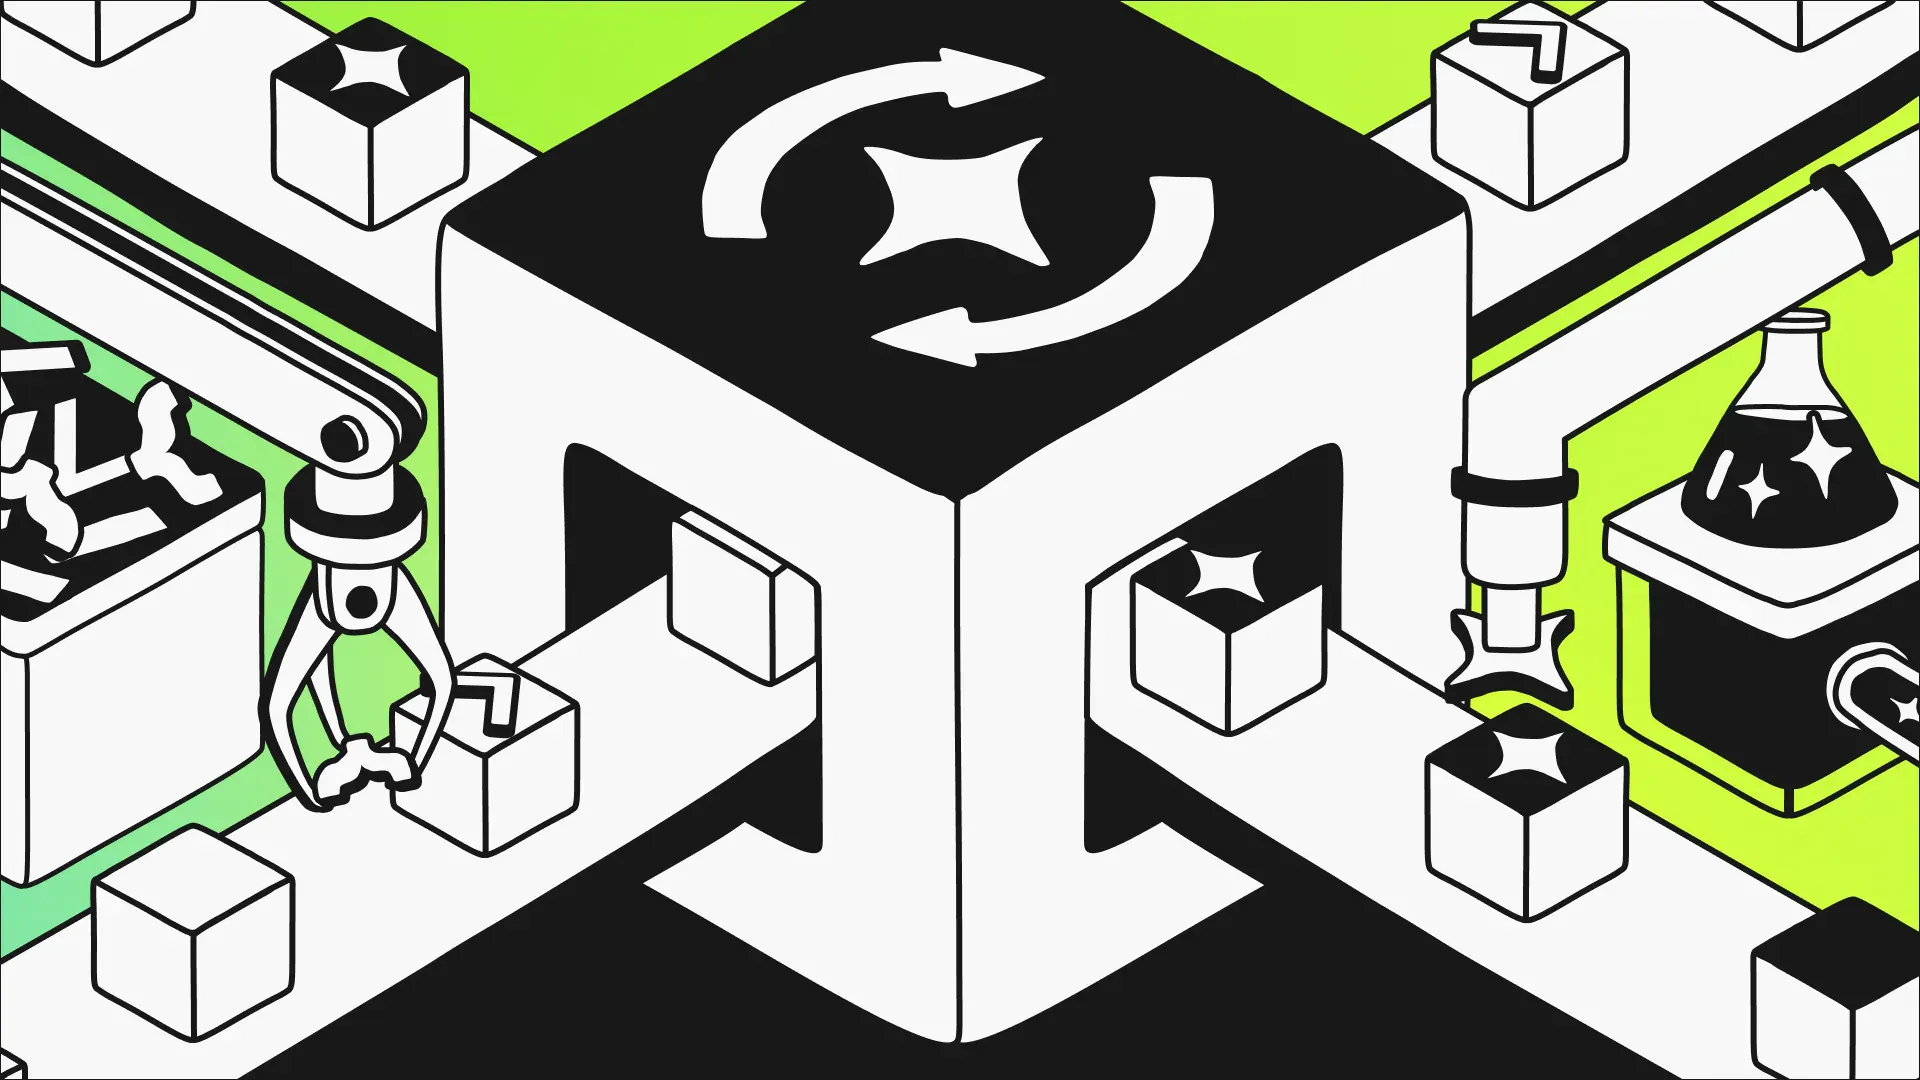
For many teams, the software factory stops at deploy. Agents generate, test, and review code, and CI/CD pipelines carry it the rest of the way. But getting code to production is not the same thing as delivering software to customers, and that last mile is where factories typically fall short. A deployment puts code into production, while a release determines who is exposed to each change and what happens when it doesn’t work as intended.
For agents to ship code directly to production, factories need three capabilities that most of them lack. The first two are familiar release practices. The third—scalable, automated guardrails—is what makes them work at agent speed.
Control over each change, not just each deploy
CI/CD and progressive delivery tools can automate deployments, traffic shifting, monitoring, and code rollback. But these controls often operate at the deployment level, rather than providing independent control over individual features or changes within it. At AI speed, a single deploy can contain dozens or hundreds of changes, and rolling back the deploy means rolling back all of them, including the ones that work.
Change-level controls, such as feature flags, help solve this problem by separating deploy from release. A flag controls who sees each change, and if something goes wrong, that change can automatically be turned off in milliseconds without a redeploy.
The ability to measure the impact of each change in production
Observability can help teams detect and diagnose production issues. But when a deployment contains multiple changes, it can be difficult to isolate the impact of a specific change, whether it’s causing problems or delivering value. Factories need to connect production performance to individual changes, with clear health metrics and thresholds that inform whether a change moves forward.
Automated guardrails that scale with AI volume
Today, release controls typically require manual work. Engineers decide which changes need a feature flag, configure how changes will be progressively rolled out, select health metrics, monitor releases, respond to regressions, and clean up flags after the work is done. As the volume of agent-written code grows, these manual steps become harder to scale, and the release work becomes the next bottleneck. Release practices can become inconsistent, leaving some changes without the safeguards they need.
Factories will remain constrained as long as every change requires a human to manually apply controls, evaluate production impact, and decide what happens next. The way forward is to give agents deterministic tools to roll out each change within policies and guardrails defined by engineers. That’s what allows release to scale more safely with agent-written code volume.
What it looks like to release at agent speed
The goal of release automation is to sustain the speed of AI-assisted coding and testing through release and into production, without sacrificing safety. Engineers define release plans, health thresholds, and guardrails. Agents then use release tools to apply the appropriate controls, manage rollouts, and respond to regressions when thresholds are breached. Teams can start by reviewing and approving flag and release recommendations, then progressively automate execution as they validate that the policies and guardrails are producing the intended outcomes.
This approach helps reduce the risk of releasing agent-written code to production without adding manual toil that slows teams down. Engineers can spend less time on release logistics and focus instead on architecture, complex customer problems, and technical trade-offs that require human judgment.
The automated release process consists of six stages, each carried out within human-defined boundaries:
Stage 1: Assess the change risk. Evaluate the risk of each change, determine whether it warrants a feature flag or additional safeguards, and, when needed, recommend a progressive release plan suited to the change and its audience.
Stage 2: Apply safeguards. When a change warrants it, create a flag, wrap the code, set health metrics and rollback thresholds, and configure the rollout strategy.
Stage 3: Control exposure. Execute the predefined release strategy, progressively increasing exposure as the change proves safe.
Stage 4: Observe production impact. Continuously evaluate each change against the predefined health and success metrics, thresholds, and guardrails.
Stage 5: Respond automatically. Pause or automatically roll back if thresholds are breached.
Stage 6: Clean up. Open a PR to remove temporary flags and old code from the code base when a release is complete.
Runtime control is the foundation for every stage of this process, and it’s the missing piece of most software factories. It integrates with the systems teams already use to build, test, and deploy software, enabling them to control how changes reach customers, measure change-level impact in production, and act on the results in milliseconds. When those controls are applied automatically to every change that needs them, agents can ship more safely at full speed.
How we’ve built our own software factory
When we set out to build a software factory at LaunchDarkly, our goal was to increase the amount of valuable software delivered per unit of human attention. Since then, we’ve more than doubled the number of PRs we merge to our production apps while reducing our major and critical incident time by 70%. And we’ve done this with roughly the same number of engineers.
We didn’t get these results overnight. It took a year of identifying bottlenecks and speeding up the processes behind them. Sometimes that meant automating a decision we kept making the same way, and sometimes it meant getting a change in front of the right person sooner. All of this started with a question: Where was our engineers’ time going?
Starting with measurement
The SDLC is one big loop, from spec to production feedback, and each stage inside it runs smaller loops of its own, like revising code until the review checks pass. To understand what to automate, we tracked how long each loop took and formed an opinion on what good output was. We then looked for the loops where getting faster or improving quality would make the biggest difference.
The first bottleneck we focused on was review. As coding agents became more embedded in our workflows, PR volume climbed and review times got longer. Automated review tools like Devin and Meticulous helped, but engineers were still manually approving a steady stream of changes that every reviewer, human or agent, agreed were fine. Those low-risk changes took a median of 5.3 hours to merge.
Automating low-risk merges
That steady stream of approvals suggested that this process was ready to be automated, but we needed a reliable way to differentiate low-risk changes from the rest.
We defined what low, medium, and high risk looked like for our codebase and set up an agent to classify each PR against those definitions. Then, we tested it against roughly 6,000 PRs from the previous six months, and found that its risk ratings matched our human reviewers’ on every single one. The only bug it would have missed had been missed by human reviewers, too. That was the evidence we needed to stop requiring human approval for low-risk changes.
Low-risk changes now merge automatically after they clear our review and security agents, while medium- and high-risk changes are reviewed by humans. We also calibrate a sample of PRs against human judgment on a monthly basis to make sure that our PRs are being classified appropriately. Today, more than 20% of our PRs ship directly to production this way, and the median time to merge a low-risk change has fallen to 57 minutes.
Extending automation into release
Taking low-risk changes off our reviewers’ plates gave them more time for the medium- and high-risk changes that needed their judgment. But review was only part of the manual work. Engineers still had to decide which changes needed a flag, add those flags by hand, define rollout plans and guardrail metrics for the riskier ones, and clean up old flags after they’d done their job.
As our PR volume kept climbing, that manual release work became the next bottleneck. So we asked ourselves: Could automation determine when a change needed release controls, apply the right flag and release strategy, monitor production health, and respond to regressions, all within guardrails our engineers define?
Our answer to that question is Release Autopilot, a set of capabilities that gives agents the power to safeguard changes all the way to production while keeping humans in control. Over the past year, our monthly feature flag creation has grown 3.7x, outpacing the 2.1x growth in merged PRs. CI now creates more than 20% of our new flags automatically, and a cleanup agent handles 42% of removals, so the growing flag count turns into less tech debt.
Flags are the first layer of the safety net. Guarded releases, which are now included in Release Autopilot, roll a flagged change out in stages and compare the users who get it with the ones who don’t. For example, if a new login screen leads to fewer successful sign-ins for its first audience, the release can automatically roll back before more users are affected. Over the last six months, this approach has caught and contained more than ten regressions before they reached all of our users.
Getting to good decisions faster
At every stage of our factory journey, the goal has been to get to a good decision faster. We automate a decision after we’ve seen it go the same way enough times to trust it, and only where the stakes allow.
As a result, our engineers no longer get pulled into endless review of agent-written changes or have to hand-manage as many release steps. They can focus on the work that needs their judgment. They’re also producing far more than they did a year ago, and because review and release now keep pace, more of that work reaches customers. Our product delivery points, an internal measure similar to story points, are rising about 20% a quarter.
If you’re building your own factory, don’t let it stop at deploy. Start by measuring your workflows, automate what you’ve proven you can trust, and keep going until that automation carries changes safely into production.
Learn more about Release Autopilot. Try it for free today; certain features in beta.